Skip to yearly menu bar Skip to main content


Keynote Oct 6, 9:00 AM - 10:00 AM Grand Ballroom

Lessons from Robots for Developing Reliable LLMs

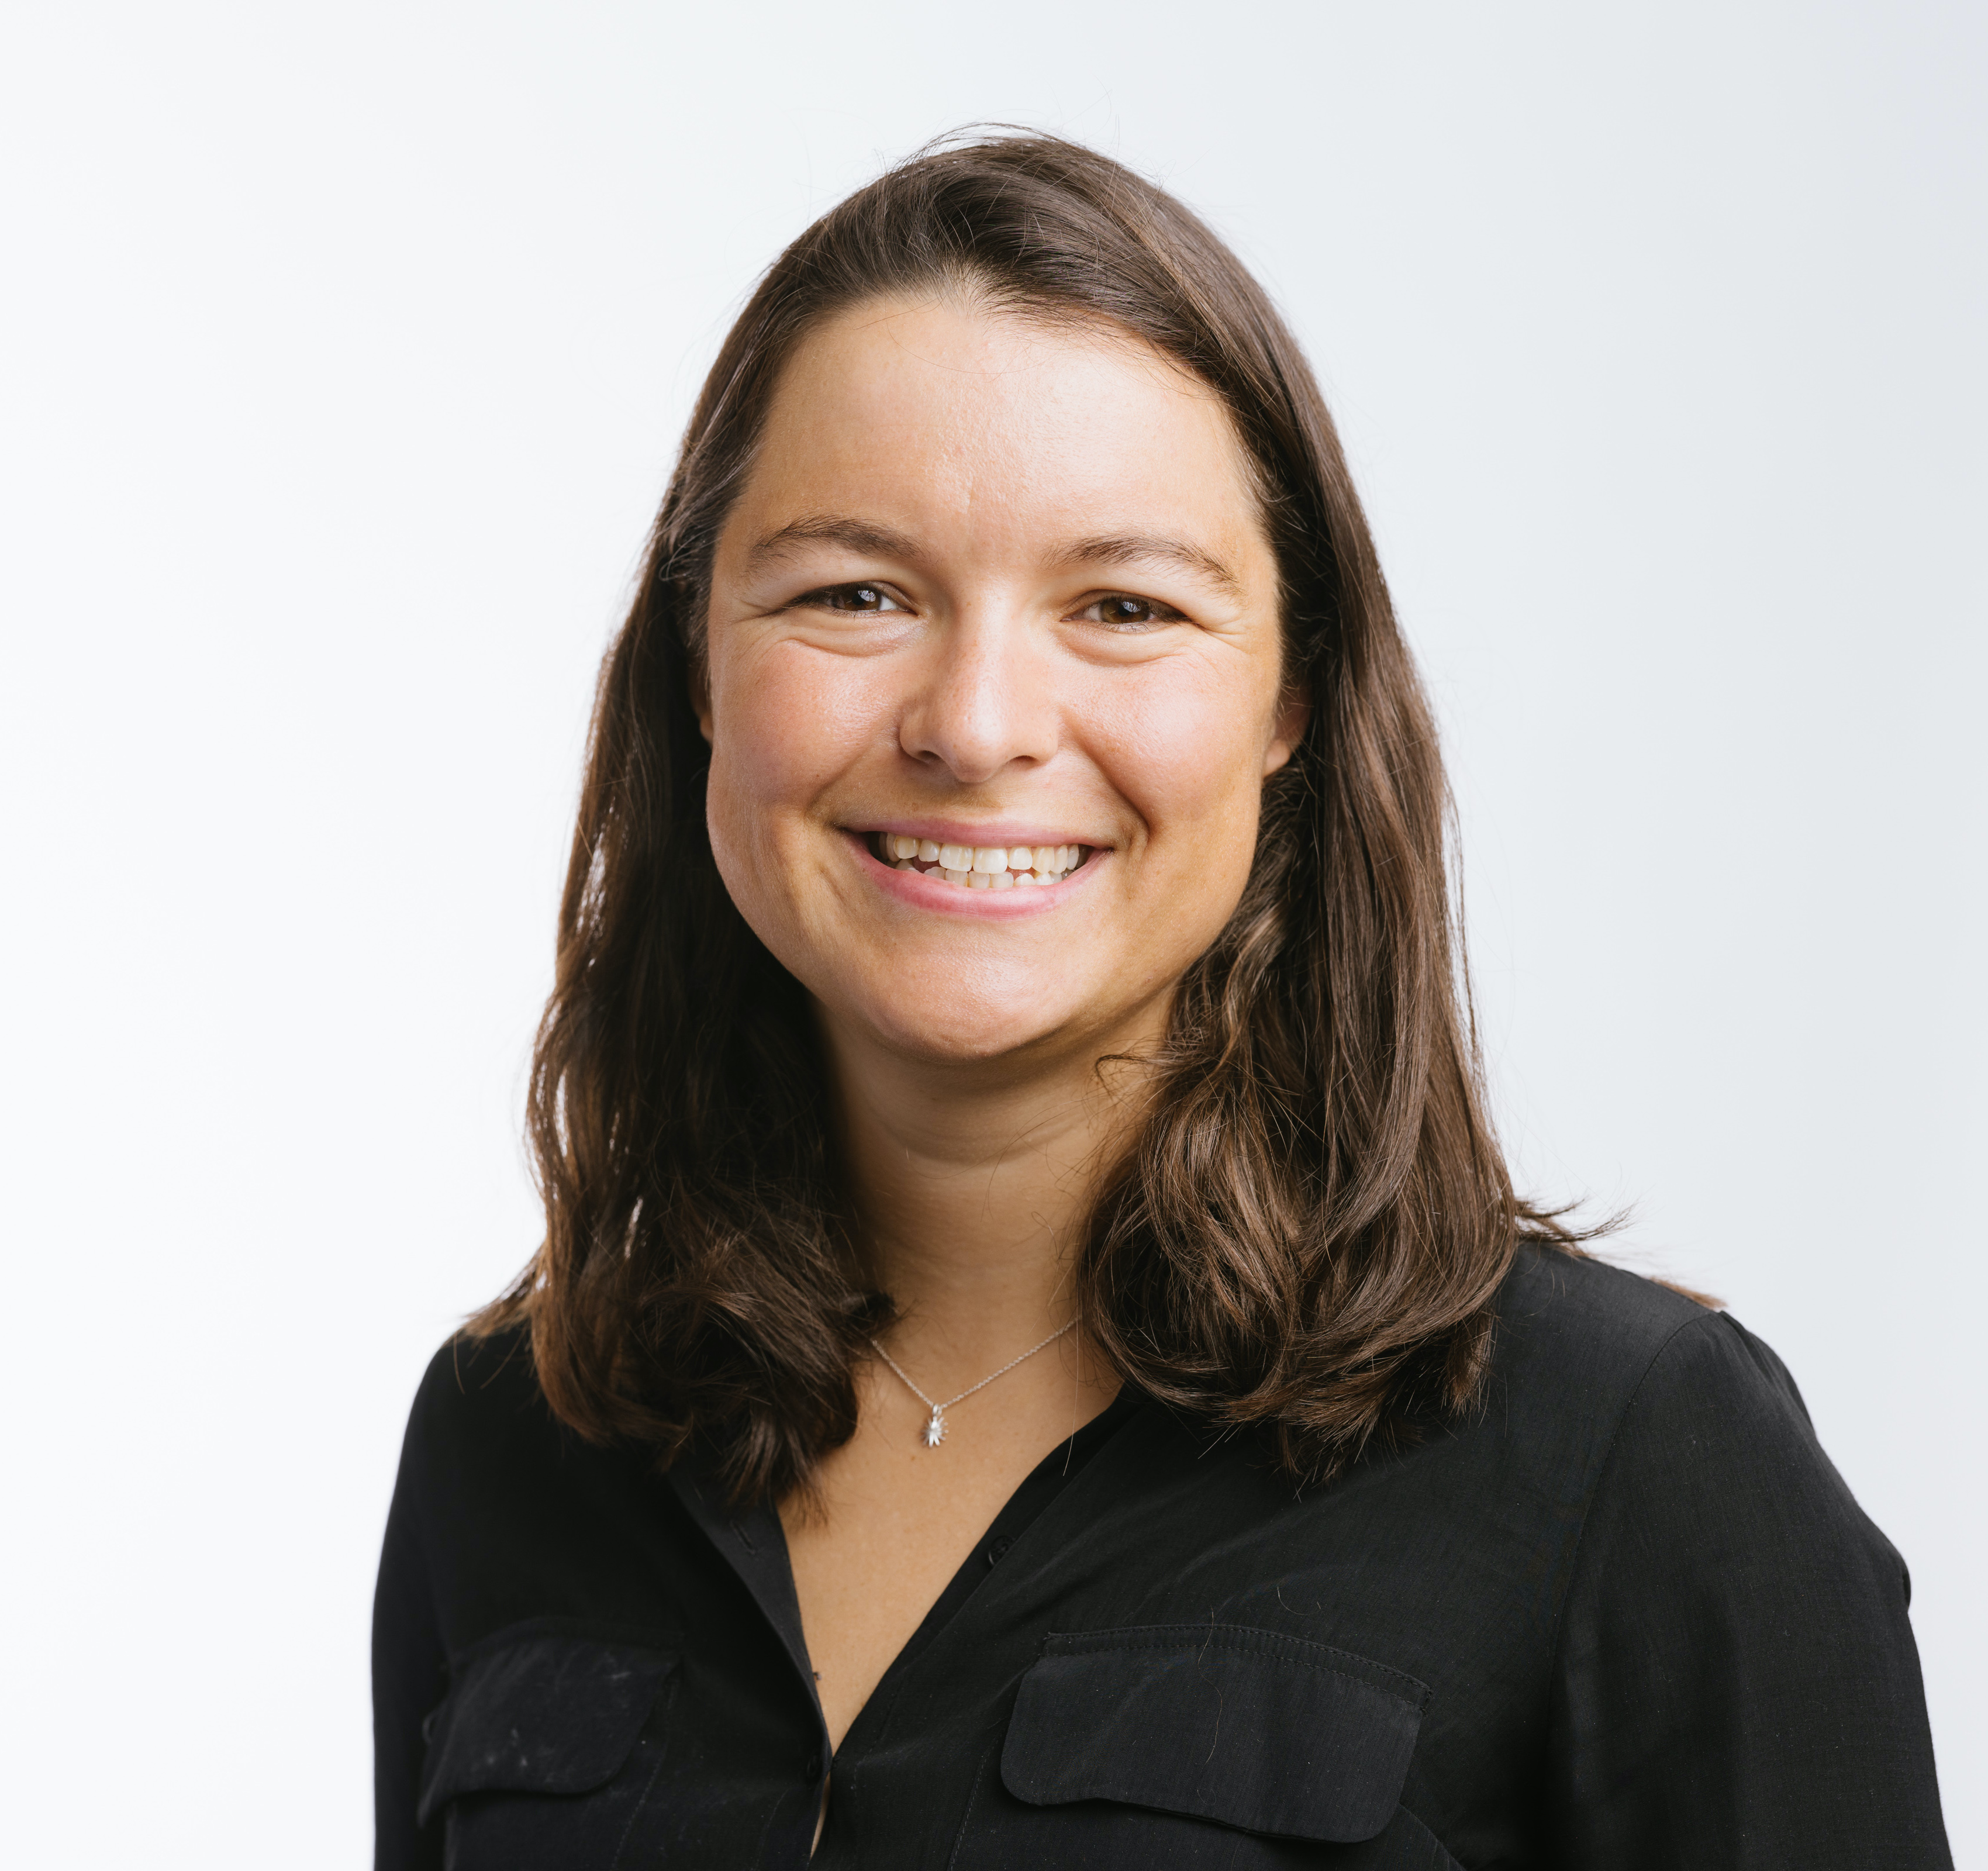
Chelsea Finn
Chelsea Finn is an Assistant Professor in Computer Science and Electrical Engineering at Stanford University and a co-founder of Physical Intelligence (Pi). Her research interests lie in the capability of robots and other agents to develop broadly intelligent behavior through learning and interaction. To this end, her work has pioneered end-to-end deep learning methods for vision-based robotic manipulation, meta-learning algorithms for few-shot learning, and approaches for scaling robot learning to broad datasets. Her research has been recognized by awards such as the Presidential Early Career Award for Scientists and Engineers, the Sloan Fellowship, and the ACM doctoral dissertation award, and has been covered by various media outlets including the New York Times, Wired, and Bloomberg. Prior to joining Stanford, she received her Bachelor's degree in Electrical Engineering and Computer Science at MIT and her PhD in Computer Science at UC Berkeley.
Reliability is one of the biggest open challenges in AI today. Despite the ubiquity of language models in society today, they still make frequent mistakes that render human review essential for a broad range of applications. In this talk, I will discuss lessons from robotics that can teach us something about the challenges faced in language model development, specifically around alignment, observability, and manual engineering, and how those lessons can translate to improvements in language model systems.
View full details
Keynote Oct 6, 2:30 PM - 3:30 PM Grand Ballroom

Neutrality Without Neutral Models

Jennifer Pan
Jennifer Pan is the Sir Robert Ho Tung Professor of Chinese Studies, Professor of Communication and a Senior Fellow at the Freeman Spogli Institute at Stanford University. Her research uses experimental and computational methods with large-scale datasets on political activity to answer questions about the role of digital media in politics, including how political censorship, propaganda, and information manipulation work in the digital age and how preferences and behaviors are shaped as a result. She is the author of Welfare for Autocrats: How Social Assistance in China Cares for its Rulers (Oxford University Press, 2020). Her work has appeared in peer-reviewed publications such as the American Political Science Review, American Journal of Political Science, Journal of Politics, Science, and Nature.
Political neutrality in AI is impossible. What does that mean for the effects of AI on political persuasion? My research on information control in China offers an unexpected vantage point for examining the politics of generative AI. Biased models can persuade, much as propaganda does in China and other authoritarian regimes. But persuasion requires exposure. In competitive information environments, exposure is contested. A large body of research on political campaigns finds small, and often null, effects of advertising, canvassing, and other persuasion attempts, despite enormous resources devoted to them, in environments where people encounter many competing messages. Understanding that exposure, not persuasiveness, is what limits media effects changes how we should approach political neutrality in AI. Neutrality may be unattainable in any single model, but it can be approximated at the level of the ecosystem, through diverse models, viewpoints, and sources. What the Chinese government has done, in its efforts to control digital information and now in generative AI, is restrict diversity at the ecosystem level. This suggests that the central political risk of AI is not that any single model is biased, but that the ecosystem becomes politically homogeneous.
View full details
Keynote Oct 7, 9:00 AM - 10:00 AM Grand Ballroom

Research at AI Speed

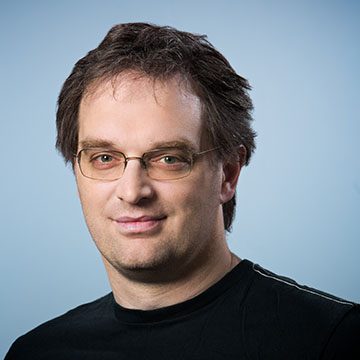
John Langford
John Langford is a Partner Research Manager at Microsoft Research. He studied Physics and Computer Science at the California Institute of Technology, earning a double bachelor’s degree in 1997, and received his Ph.D. from Carnegie Mellon University in 2002. Since then, he has worked at Yahoo!, Toyota Technological Institute, and IBM‘s Watson Research Center. He is also the primary author of the popular Machine Learning weblog, hunch.net and the principle developer of Vowpal Wabbit. Previous research projects include Isomap, Captcha, Learning Reductions, Cover Trees, and Contextual Bandit learning.
We as a field are experience the industrialization of innovation generating structural changes to the process and outcomes of research and development. Where we are we in this process? How do you navigate the process? What are the failure modes and what does success look like? How can we organize effectively to work with a process of industrial innovation?
View full details
Keynote Oct 8, 9:00 AM - 10:00 AM Grand Ballroom

Large Language Models are Culture Machines

Henry Farrell
Henry Farrell is the SNF Agora Professor of International Affairs at Johns Hopkins School of Advanced International Studies, an External Professor at the Santa Fe Institute, and the 2019 recipient of the Friedrich Schiedel Prize for Politics and Technology. He is a member of the Council on Foreign Relations, and a Council Member of the European Council on Foreign Relations, as well as an affiliated scholar at Stanford University Law School’s Center for the Internet and Society, and an international correspondent for Stato e Mercato.
Our modern mythologies about LLMs distract us from what they have in common with actual human myths. Instead of being a big step on the road towards autonomous individual intelligence, LLMs compress extensive corpora of collectively generated human cultural knowledge, enabling new uses of myths, traditions, stock elements, formulas, nostrums, tropes and collective rules-of-thumb. This may have unexpected uses: a decade ago, few would have anticipated that the creativity of the bard and the creativity of the programmer had much in common. LLMs are automated culture machines, but humans have constructed non-automated culture machines in the past. We can learn a great deal about LLMs' limits and potential from studying previous culture machines such as Homeric epics, folk tales and structuralist literary experiments.
View full details
Keynote Oct 8, 2:30 PM - 3:30 PM Grand Ballroom

Is NLP System-Building a Machine Learning Problem?

Jason Eisner
Jason Eisner is Professor of Computer Science at Johns Hopkins University and a Fellow of the Association for Computational Linguistics. At Johns Hopkins, he is also affiliated with the Center for Language and Speech Processing, the Mathematical Institute for Data Science, the Cognitive Science Department, and the Data Science and AI Institute. His goal is to develop the probabilistic modeling, inference, and learning techniques needed for a unified model of all kinds of linguistic structure, and to connect existing models (such as LLMs) to commonsense reasoning, formal reasoning, and downstream applications. His 180+ papers have presented various algorithms for parsing, machine translation, and weighted finite-state machines; formalizations, algorithms, theorems, and empirical results in computational phonology; unsupervised or semi-supervised learning methods for syntax, morphology, and word-sense disambiguation; and principled methods for conversational AI, including neural language modeling and semantic parsing. From 2019-2024 he was Director of Research at Microsoft Semantic Machines, which developed new approaches to conversational AI. He is also the lead designer of Dyna, a declarative programming language that provides an infrastructure for AI algorithms. He has received 3 school-wide awards for excellence in teaching, most recently in 2025, as well as recent Best Paper Awards at ACL 2017, EMNLP 2019, and NAACL 2021 and Outstanding Paper Awards at ACL 2022, EMNLP 2024, and COLM 2025.
Everyone nowadays is building and evaluating LLM workflows. It's easy to get something running, but we don't yet have an engineering discipline for zeroing in on the most accurate and cost-effective system. There are many ways to break a given task into subtasks -- each of which may benefit from evaluation and revision. There are many components to try, including prompts, examples, rewards, LLMs, and external tools -- as well as humans in the loop, human annotators before the loop, and human evaluators after the loop. Many of these components are trainable or configurable and have varying costs. Do we really have to search this space by hand? Or could AI guide our use of annotation and computation? The problem is more general than NLP. For example, medicine develops workflows for diagnosis and treatment. I'll outline a general approach based on active feature acquisition: every human annotation, LLM output, tool call, or medical test result is a random variable that we could pay to observe. Since random variables are often correlated, observing cheap variables can help us predict more expensive variables and evaluate whether they are worth observing as well. (Which step should we try next, and with what prompt? Should we double-check or revise the result? Should we ask a human?) Ultimately, gathering information is a reinforcement learning problem. I'll describe how to train an environment model that predicts distributions over any missing variables, much as BERT predicts distributions over any missing tokens. This model could be extended into a policy model that chooses which missing variable to observe next. Any data gathered by the system can immediately be used to train it further, including on counterfactual trajectories, which exploit the fact that our actions have no side effects (observing variables does not change the values of other variables).
View full details

No Events Found

Try adjusting your search terms